Six days with agents, 14 to 20 months for people.
An effort analysis of Proven, the open-source code reviewer one person and a fleet of AI coding agents built at the Open Agent Hackathon in October 2026. We measured what was delivered, then estimated with four published methods what a conventional team would need to build the same thing. Every number can be checked in the public repository.
The comparison
| Built by the agent fleet | Estimated for a human team | |
|---|---|---|
| Calendar time | Built by the agent fleet139 hours, from the first build commit to the submission | Estimated for a human team14 to 20 months |
| People | Built by the agent fleet1 owner who decides and merges and writes no code, and a fleet of AI agents | Estimated for a human team9 to 11 full-time people in 8 roles |
| Effort | Built by the agent fleetnot comparable in person-months | Estimated for a human team100 to 225 person-months, central estimate 135 to 180 |
| Production code | Built by the agent fleet42,036 lines of Go, plus 9,246 lines of shell, TypeScript, Python and SQL | Estimated for a human teamthe same scope |
| Tests | Built by the agent fleet58,956 lines of Go, 1,828 test functions | Estimated for a human teamthe same scope |
| Record | Built by the agent fleet53 architecture decision records; 307 review verdicts in 154 independent reviews, 113 of them rejections | Estimated for a human teamusually partial: pull-request comments and tickets |
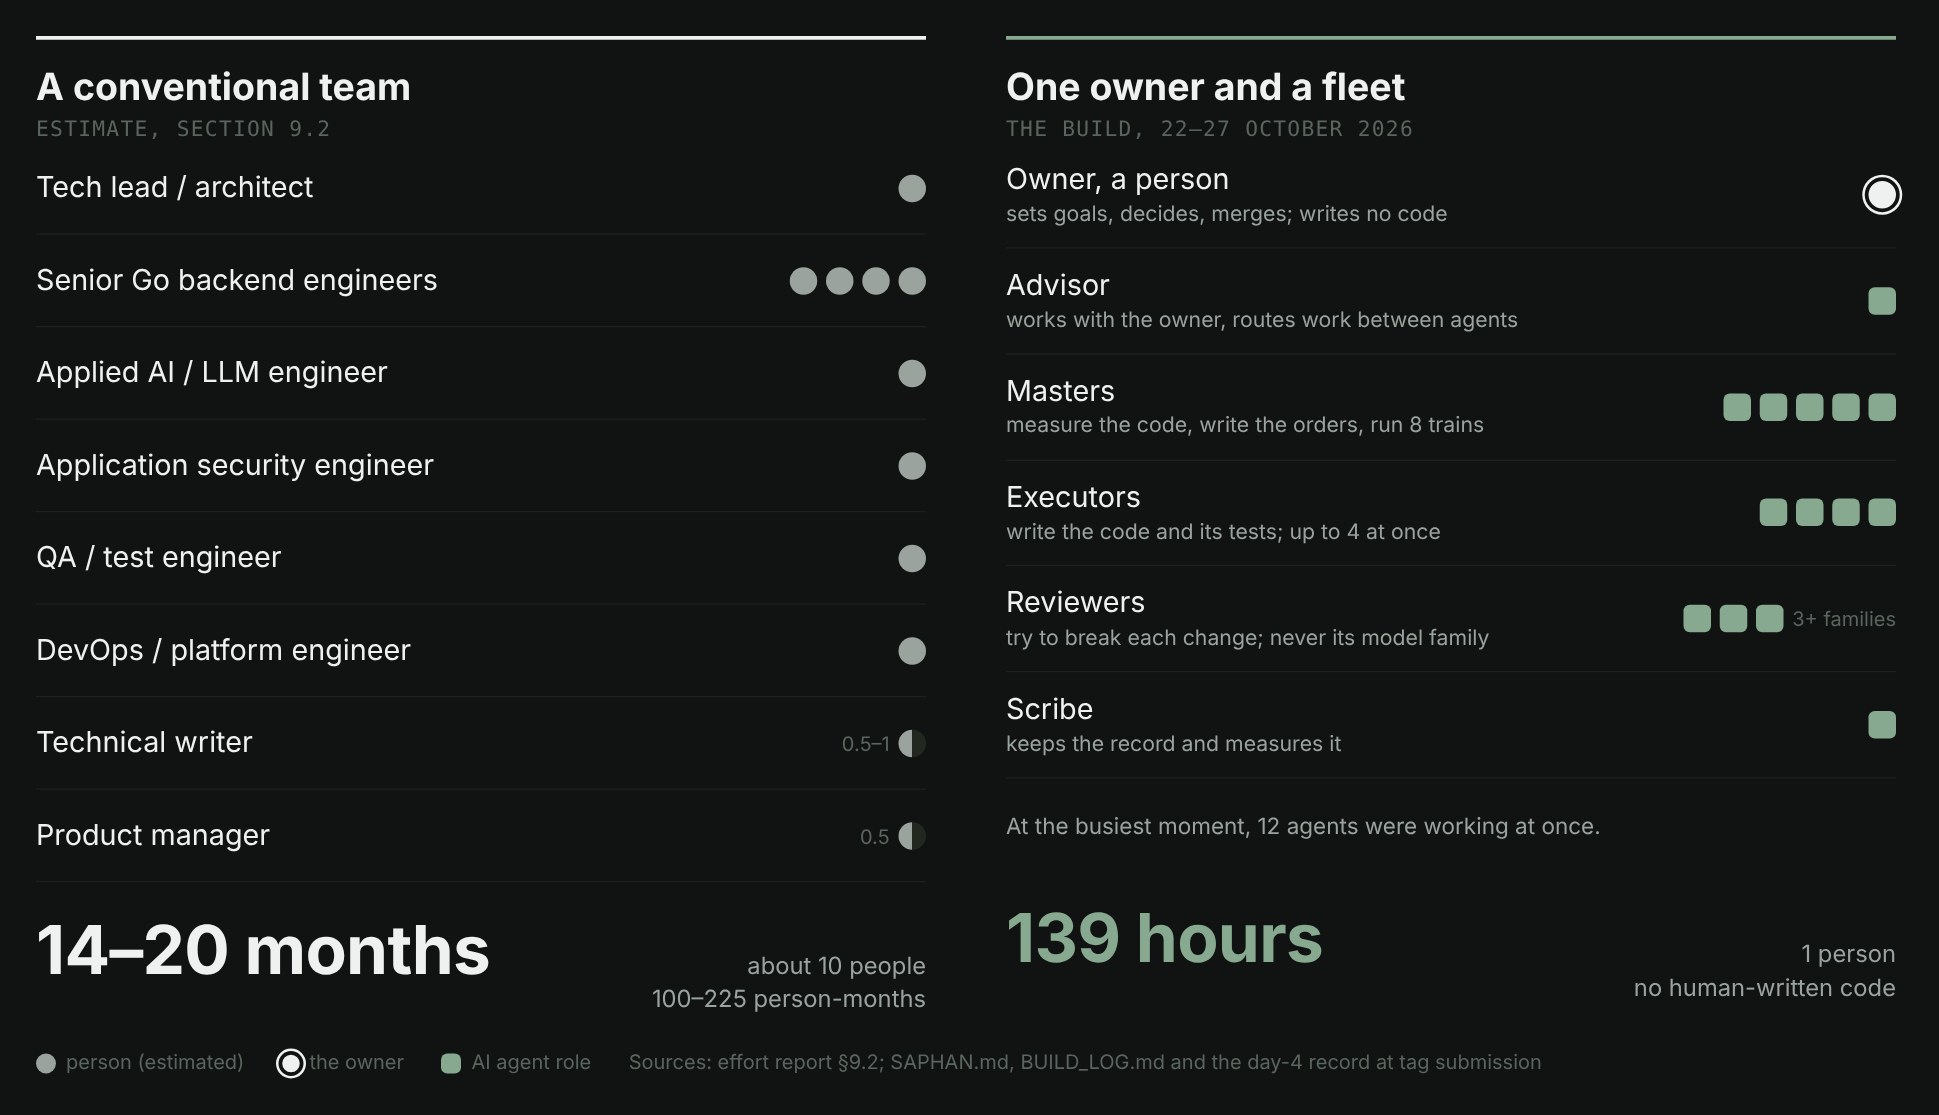
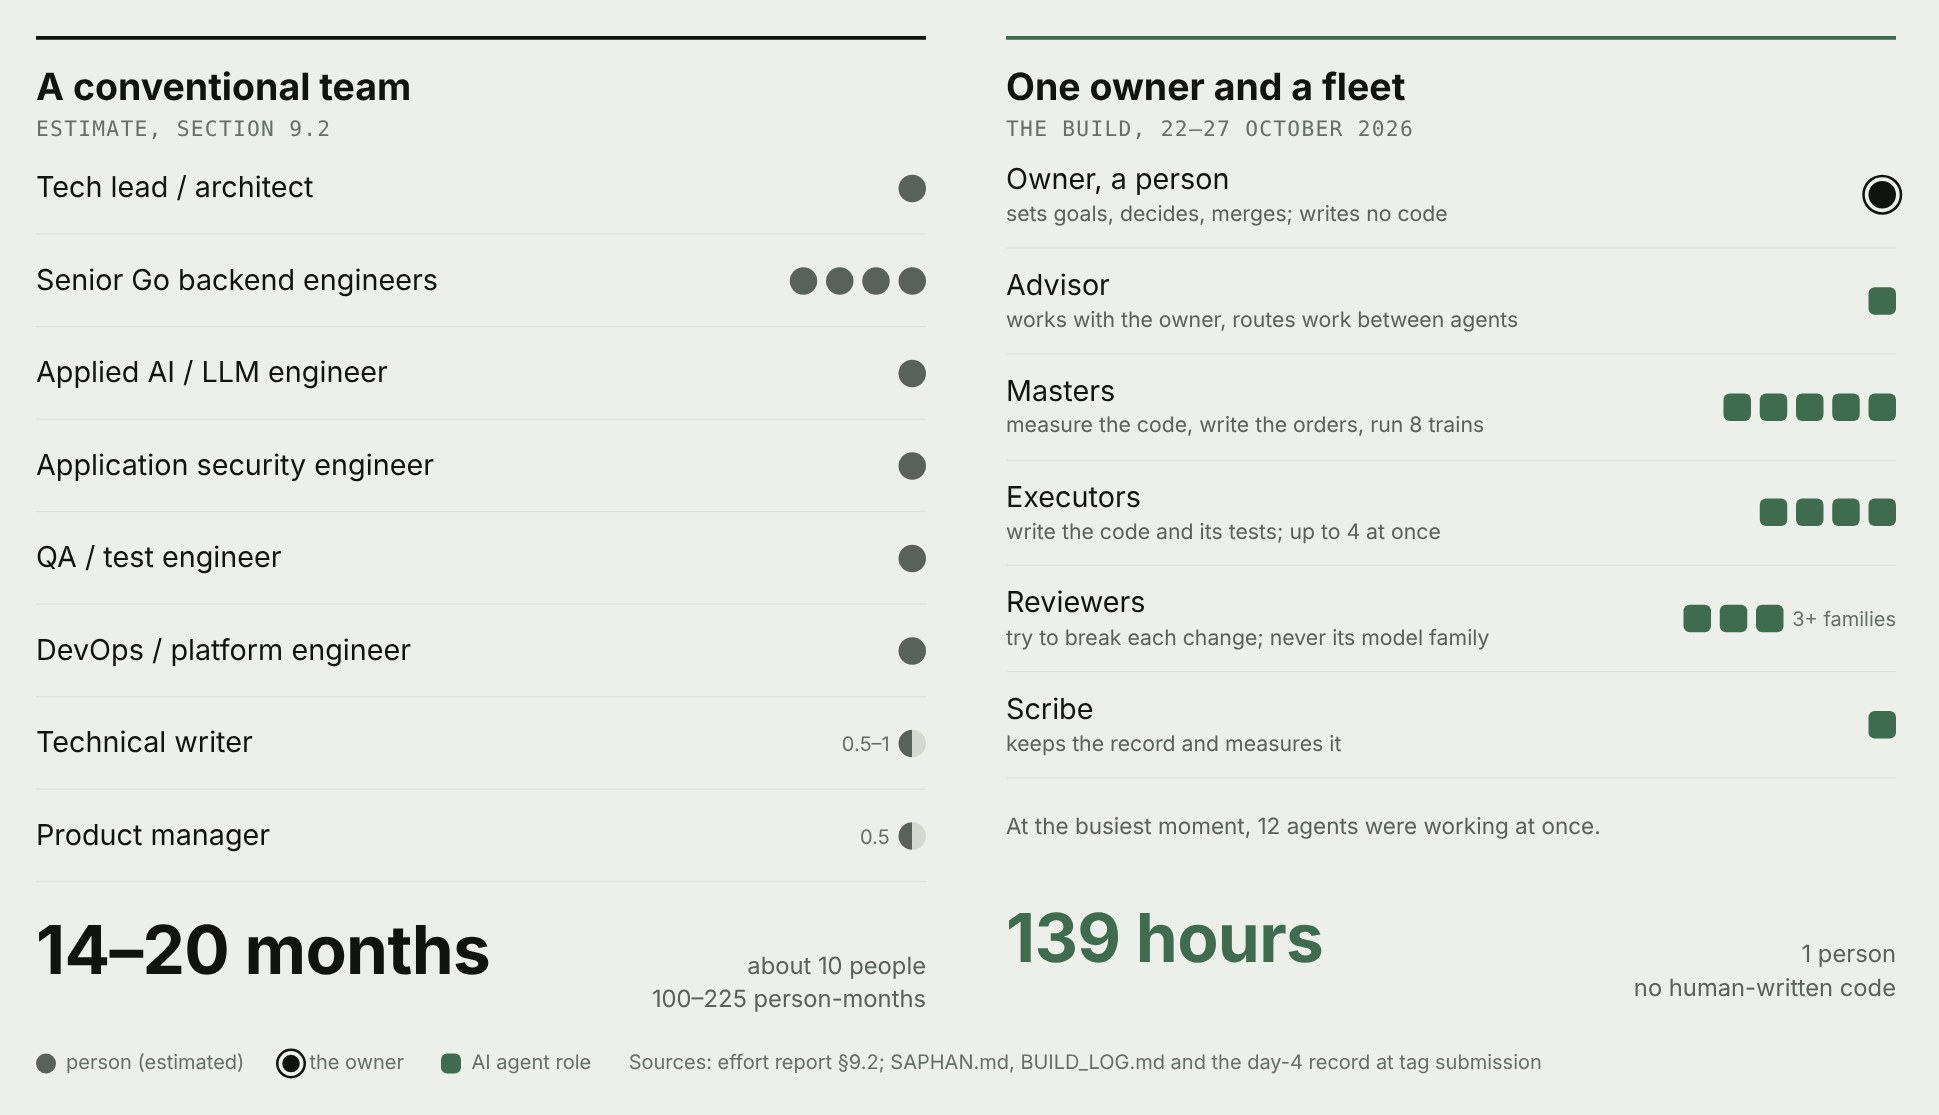
The estimate comes from COCOMO II, QSM's database of completed projects, Steve McConnell's productivity ranges and a bottom-up count by work package. The comparison is about calendar time and scope, not about whether agents are better programmers.
Code quality, against published baselines
Test coverage: 80.9%
Above the 75% of level 4 in Google's voluntary coverage levels (Ivanković et al., 2019). Measured on the packages that hold 64% of the production code; the report explains why.
Documented public API: 96.1%
Of the exported Go identifiers, 1,490 of 1,550 have a doc comment. Go's guidance asks for every one.
Comment density: 18.7%
The mean across more than 5,000 open-source projects is 18.67% (Arafat and Riehle, 2009).
Complexity: 88.9% of functions at or below 10
McCabe's limit per function (NIST SP 500-235). One known outlier, listed in the README under Honest limits.
What this does not claim
Lines of code measure size, not value.
The estimation models were calibrated on human projects; applying them here assumes that the same scope means the same size.
Equal quality is not proven.
The README lists open limits. A human team might have shipped fewer features with fewer known limits.
Six days is not the whole effort.
The topic and 25 design decisions came from planning on 16 to 21 October, and the fleet runs on Saphan Studio, built before the hackathon.
Not everything is measured.
The owner's working hours are not in the record, and this public edition publishes no money figures for the agent build.
Check it yourself
Section 11 of the report gives the commands for every number: clone the repository, check out the tag submission, and count. Start with Honest limits in the README, then hackathon/fleet/LEDGER.md: every change, the model that built it, its rounds and its conditions.
More of Saphan Studio
Research — study AI agents at work →Governance — decisions on the record →Protocol — how the fleet works →
Questions about the method, or want the same measurement on your team's work?
Contact us — [email protected]